Make your agents 1% better every day. Upgrade models, avoid regressions, optimize maximally.
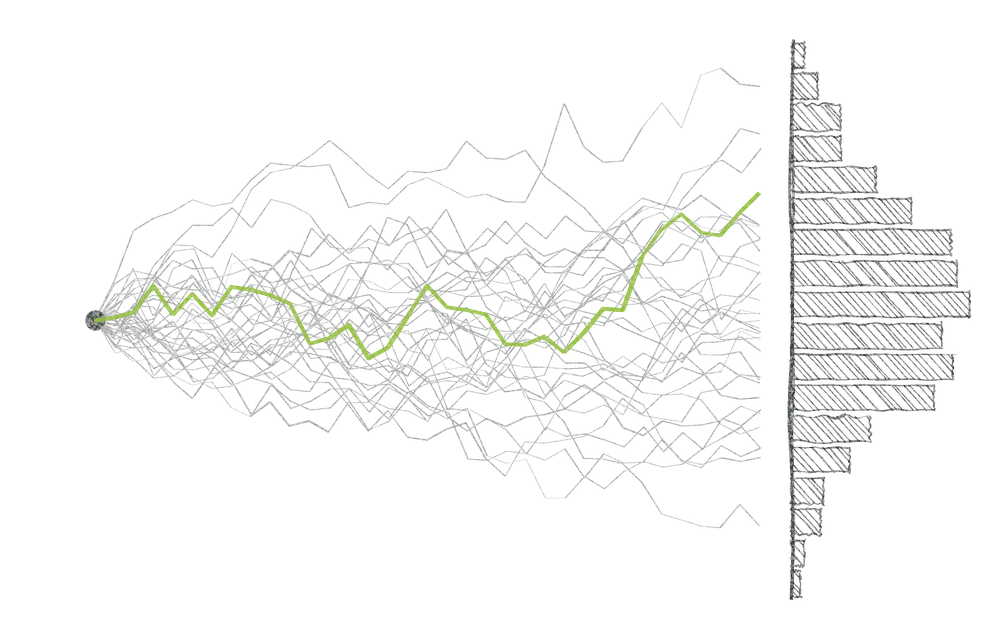
s0outcomes
Q̂ = (1/N) Σ Q(τi)
measureiteratecompound
Qt+1 = (1 + r) Qt
What could you do with 100x more eval coverage?
Detect and fix regressions faster
Safely upgrade model & agent components
Create tighter and faster optimization loops
Fine-tune models
The software
Meet the Agent Optimization Toolkit
AOT Evals is now open source. Build golden records, safe testing environments, and repeatable optimization loops. Score every change against your objective: cost, quality and speed.
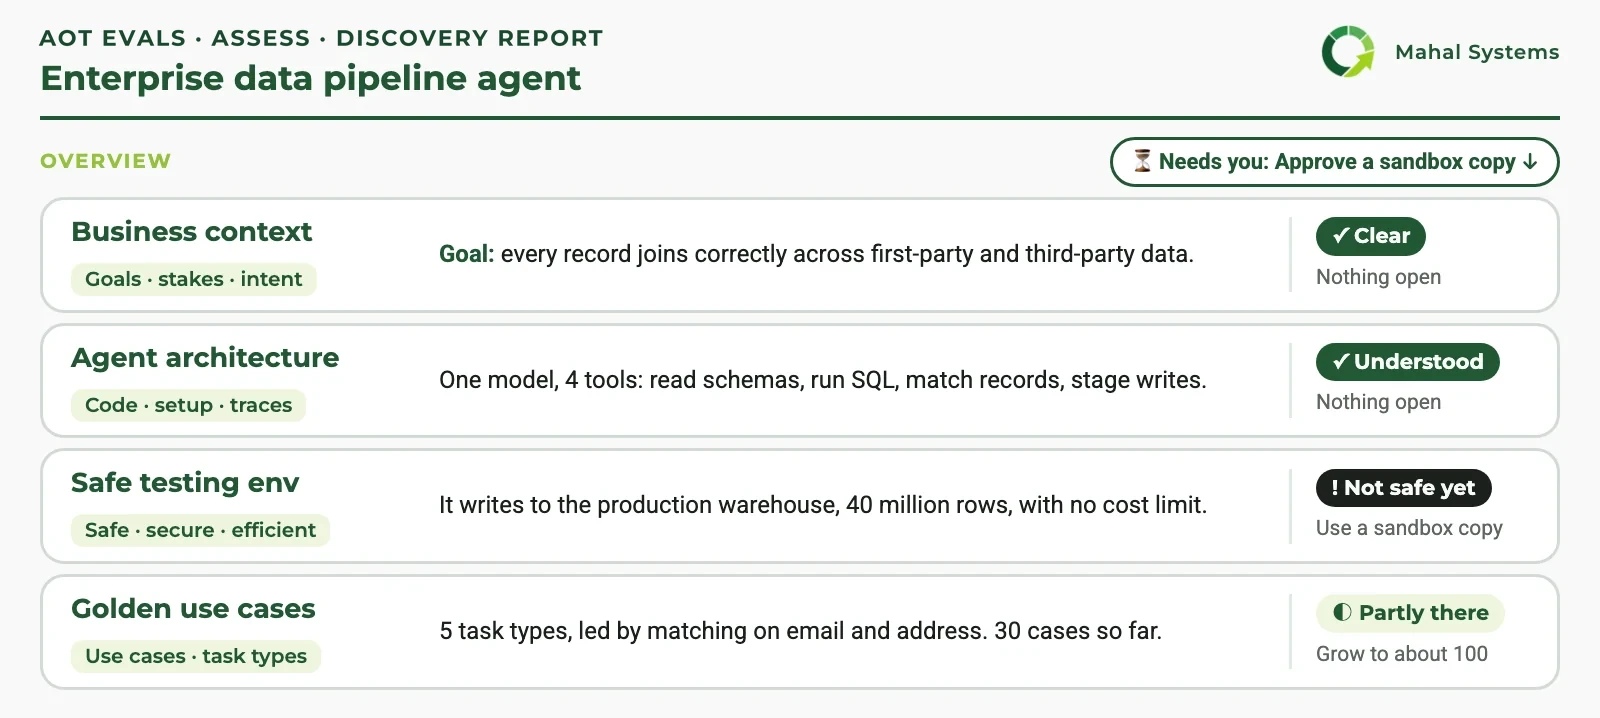
Goal: every record joins correctly across first-party and third-party data.
Agent architecture✓ Understood
One model, 4 tools: read schemas, run SQL, match records, stage writes.
Safe testing environment! Not safe yet
It writes to the production warehouse, 40 million rows, with no cost limit.
Golden use cases◐ Partly there
5 task types, led by matching on email and address. 30 cases so far.
Get started in 5 minutes
Our Solution
The three components required to build your eval pipeline
Build infrastructure to test your agent, create golden test cases and judges to score it, and bring in external graders to scale it out. Our solution provides the strategy, software & forward deployed services.
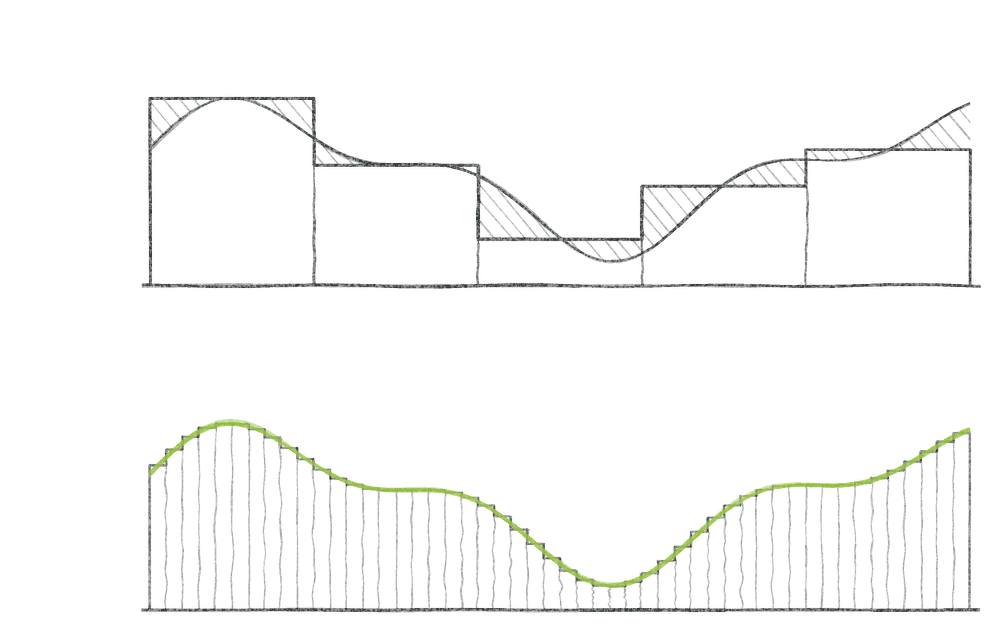
n = 5n = 50
Σ Q(xi) Δx → ∫ Q(x) dx
Agent Testing Infrastructure
Create a realistic, secure copy of your system and grade what the agent did, not just what it said. Let the agent read anonymized data, write to a database you can reset, and call mocked APIs, so tests scale without touching production.
Q(θ)Q*(θ)
Golden Test Cases & Judges
Size your test cases for statistical significance, with the arithmetic shown before anyone labels. Calibrate LLM judges to your labels and report their error rates, so you know your evals are right.
Scaled out with external graders
Have your engineers build the suite and domain experts grade it on their own screens. Vet your graders and validate them continuously with calibration and drift checks, so you get 100x the cases you can trust.
What Great Looks Like
Our dream setup for your agent 😉
Tap any box to see what it does.Tap any box to zoom in.
AI assistHuman labels
Traces & Application Usage
Mine your existing data assets to create a comprehensive set of high quality test cases:
Agent traces from your existing observability platform
Application logs & product analytics
Notes & videos from user tests & interviews
Failures from bug / issue tracking & support queues
Agent Eval Infrastructure
Run your agent at scale in a safe, realistic copy of your environment:
Harness & sandbox runtime
Mocked outside APIs
Recorded API responses, replayed in tests
A safe database to write to & reset
Realistic, anonymized seed data
Agent Objective & Modeling
Define what better means, then measure it rigorously, backed by the proper statistics and state-of-the-art data science methods:
An objective: maximize quality within cost & speed limits
Significance testing on every difference
Misclassification breakdowns, with what each error costs
The noise floor & how many repeat runs you need
Isolated compute in your environment
Golden Test Cases
Q*(θ)
Build the trusted test set every change is scored against:
Cases broken down by category of real traffic
Deterministic checks first, because code can't be swayed
LLM judges measured against human labels
Private holdouts that optimization never touches
Grader UI
Each problem graded like a test
Question 12 of 40Example problem
Task
Refund order 4417 under the 30-day policy.
What the agent changed
orders.4417.statuspaid → refunded
Did the agent follow the policy?
APassBFail
Explain why, by note, audio or video
Design intuitive interfaces that provide maximal grading efficiency and quality for expert judges:
One problem at a time, graded like a test
What the agent changed, not just what it said
Reasons captured by note, audio or video
Every label saved as a golden test case
LLM Judges
Score not just the outcome but the work - and do so in a way that covers all dimensions relevant to your agent domain:
Qualitative dimensions like tone, brand & policy
Judge calibration via expert label analysis
Score calibration for pass / fail deployment gates
Agent Changes
Changes to your agent including bug fixes, feature development, and new use case support:
Prompt, tool, harness & model changes
New version vs. current, on the same cases
Agent Optimizations
Changes to your agent designed to improve quality, cost, and speed:
Each proposed optimization tested against your evals
Quality that climbs release by release
Model Fine Tuning
Fine-tuning of the underlying model for your agent:
Training data from your labeled cases
Tuned model vs. current, on your evals
Evaluation Engine
gainlossone column per test caseΔQ = (gains − losses) / n > MDE
Any and all changes are scored in an accurate, efficient, and quantitative manner:
Golden test & LLM judge evals on every change
Gains & losses counted case by case, on identical cases
A ship gate at the minimum detectable effect
Changes scoped to the test sets they affect
Production trace monitoring, A/B & blue-green tests
Synthetic Test Cases
Multiply your golden cases into a larger test suite:
New cases generated from your golden cases
About 10 times the size of the golden set
Validated by expert graders
Objective Monitoring
Score all agent changes against a defined objective function to monitor progress against business goals:
Quality weighted by business value & real traffic
Alignment with what the business cares about
Detection of shifts in the traffic distribution
Grader
Make sure every label can be trusted:
A calibration set passed before any label counts
Two blind labels on every run
The work behind each answer, not just the answer
Bench of Graders
1,000+ on call
Scale your expert graders without building the operation:
Graders from your customers & expert pools
Continuous quality monitoring for each grader
Contracts & payment handled for you
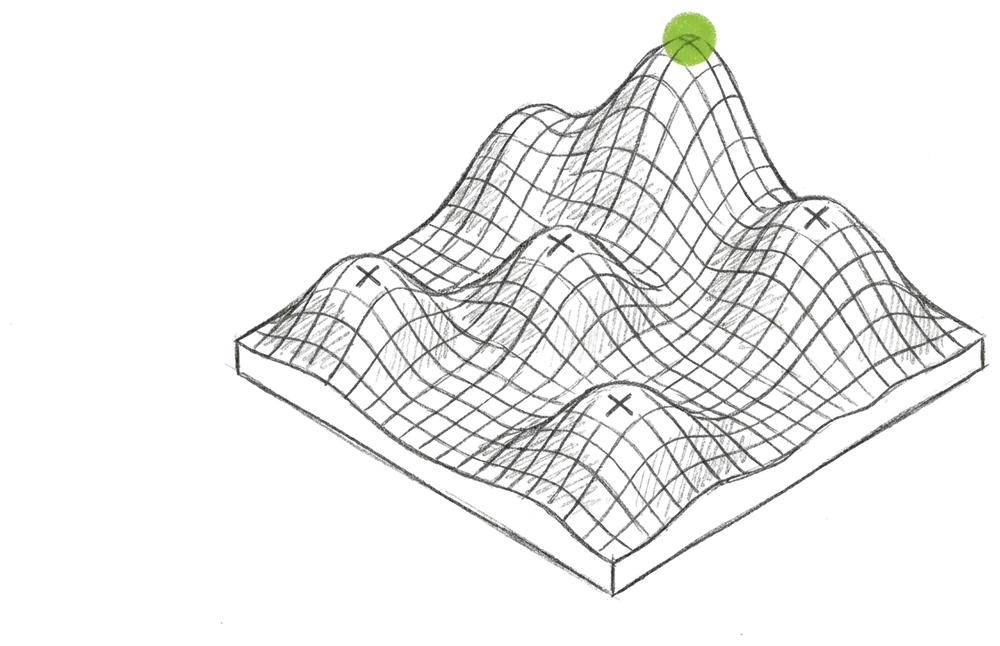
global maxlocal maxlocal max
The results
Getting this right is hard.
Need help? We're here to help you get your strategy, software, and custom solutions in place:
 Mahal Systems
 n = 5n = 50